 Verbamor
Proper nouns do 5% of the work in coverage stats
Every coverage figure you have read bundles names in with the vocabulary. Nation measured how big that bundle is across 14 texts and corpora, and it swings from 0.50% of a Henry James novel to 6.12% of an American news corpus. Which text you picked matters more than which 1,000 words you learned.
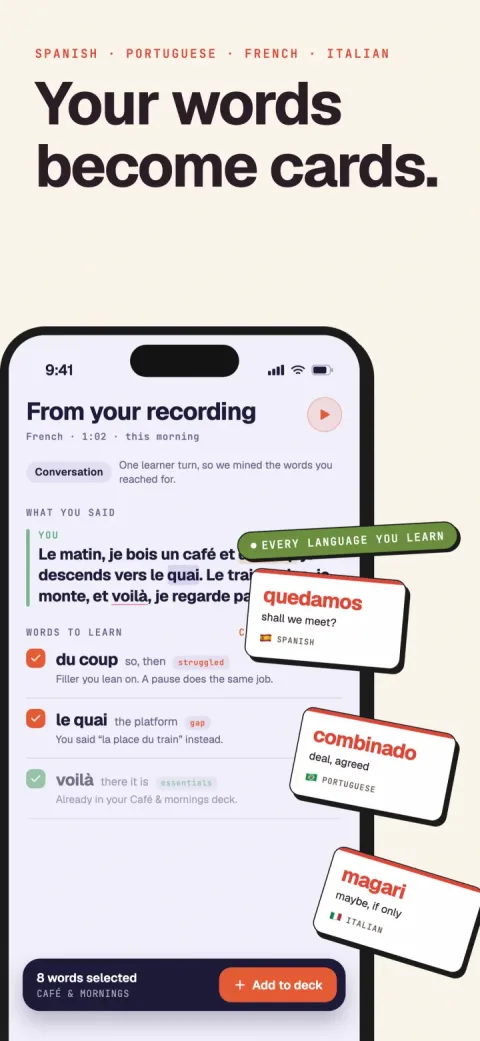
Verbamor turns the words from your own lessons and recordings into flashcards, and brings each one back before you’d forget it.
Nation's coverage figures, the share of a text's running words a vocabulary covers, come with a clause attached. It reads "plus proper nouns," and it rarely survives the trip into a blog post.
My companion post on the word-family unit covers that clause and does the subtraction on one text. This page is the part that subtraction opened up: Nation ran the same measurement on 14 separate texts and corpora (large text collections). The results spread across a range wide enough that the genre you read decides more than a year of study.
Here's the clause, from his conclusion:
The greatest variation in vocabulary coverage is most likely to occur in the first 1,000 words, and in the proper nouns. The first 1,000 plus proper nouns cover 78%–81% of written text, and around 85% of spoken text.
Nation 2006, p. 79, conclusion point 1The first sentence is the one that gets skipped. Nation names proper nouns as one of the two places his numbers move the most, so he's flagging up front that the quantity is unstable. Then everyone quotes the second sentence.
Across 14 texts, proper nouns vary by a factor of 12
Nation prints the proper-noun percentage separately for every text he profiled, as a footer row on five tables, built to be subtracted and forgotten. Pull those rows together and you get a picture the paper never assembles.
| Text | Kind | Proper nouns (%) |
|---|---|---|
| The Turn of the Screw | Novel | 0.50 |
| Conversation (Wellington) | Unscripted speech | 1.03 |
| Lord Jim | Novel | 1.04 |
| Talk-back radio, interviews | Unscripted speech | 1.29 |
| Shrek | Film script | 1.47 |
| Tono-Bungay | Novel | 1.55 |
| Lady Chatterley's Lover | Novel | 2.05 |
| The Great Gatsby | Novel | 2.12 |
| Kolaphur (Indian English) | Newspaper | 4.55 |
| LOB (British, 1961) | Newspaper | 5.29 |
| Frown (American, 1991) | Newspaper | 5.43 |
| The Picture of Dorian Gray | Graded reader | 5.55 |
| FLOB (British, 1991) | Newspaper | 5.66 |
| Brown (American, 1961) | Newspaper | 6.12 |
0.50% to 6.12%. The top of that range is 12.2 times the bottom.
Nation explains the low end himself. The Turn of the Screw "has a very small number of proper nouns because there are only four major characters in the novel."
A ghost story with a cast of four, and the size of that cast moves the coverage figure by more than five points. The high end gets an equally boring explanation: newspapers "are about people, places, and events."
Novels and newspapers don't overlap
Sorting does something the individual tables can't: the two genres separate cleanly, with a gap between them.
Five novels: 0.50, 1.04, 1.55, 2.05, 2.12. Mean 1.45%.
Five newspaper corpora: 4.55, 5.29, 5.43, 5.66, 6.12. Mean 5.41%.
The highest novel sits at 2.12% and the lowest newspaper at 4.55%, so there is 2.43 points of clear air between the two groups. Ten texts, two genres, zero overlap.
Newspapers carry 3.7 times the proper-noun load of novels. The corpora span 30 years and three countries without a single one crossing into novel territory.
A stable finding hiding in a set of throwaway rows, and it has a direct consequence.
Test yourself on a newspaper and roughly 5.4 points of your comprehension is names you were always going to recognise. Do the same test on a novel and you get about 1.5. Same vocabulary, same effort, and the score moves by 4 points depending on what you happened to open.
The graded reader is the outlier worth flagging. The Picture of Dorian Gray in the graded edition Nation profiled runs 5.55%, right in newspaper range, and it's a simplified novel.
Simplification strips vocabulary but leaves the character names alone. So cutting the text down to a 1,000-word list mechanically raises the proper-noun share of what remains. If you're using graded readers to build coverage, a chunk of the comfort is the names.
Strip the names and 98% goes away
Now the part that changes how you should read the whole paper.
Two of Nation's tables print cumulative coverage twice, with proper nouns and without, band by band through all 14,000 word families (a base word plus its inflected and derived forms). They're Table 5 for Lady Chatterley's Lover and Table 12 for Shrek.
His headline target is 98% coverage, taken from Hu and Nation (2000) as the level where unassisted reading works. So run down the without-proper-nouns column and find where it crosses 98.
It never does.
Fourteen thousand word families, the entire BNC list set he had available, and Lady Chatterley's Lover tops out at 96.96%. Shrek, a children's film, tops out at 97.78%. Within the word-family bands, the 98% threshold that anchors the whole paper is reachable only with the proper-noun block added in.
Two texts is thin evidence for a claim about a paper, and those are the only two where Nation prints both columns. But the same subtraction works on the other nine, because he gives each text a coverage figure including names and a proper-noun row of its own. Take one from the other.
At 9,000 families plus names, four of his five novels land under 98% once the names come out: Lord Jim 97.02, Lady Chatterley's Lover 96.17, The Great Gatsby 96.35, Tono-Bungay 96.45.
The exception is The Turn of the Screw at 98.02, and it clears only because its name count is 0.50%, the lowest in the set.
The newspapers are worse. At 8,000 plus names, stripping the names puts all five between 91.48% and 93.50%, every one of them 4.5 to 6.5 points short.
Eleven texts, then. Ten fail Nation's own threshold once his own proper-noun row comes out, and the one that passes is the ghost story with four characters in it. That's arithmetic on rows he printed, and he presents it nowhere.
The precise boundary matters, so here it is. Both tables carry a final row for words outside all 14 lists.
Add that row and the without-names column reaches 97.92% for Lady Chatterley's Lover, still short, and 98.53% for Shrek, which clears it.
So the honest statement is narrower than "98% is impossible without names". It's that no quantity of studied word families gets either text there. Shrek only crosses once you also count words that appear on no frequency list at all, and that isn't a study target anyone can act on.
So "8,000 to 9,000 word families gets you to 98%" is a claim about 8,000 word families plus every name in the book.
How much work is that block doing? For Lady Chatterley's Lover, the proper-noun bundle is worth 2.05 points. Compare that against what the individual thousand-word bands buy at the same point in the curve:
| Band | Extra coverage (%) |
|---|---|
| 2nd 1,000 | 7.21 |
| 3rd 1,000 | 3.14 |
| 4th 1,000 | 1.78 |
| 5th 1,000 | 1.07 |
| 6th 1,000 | 0.69 |
| 7th 1,000 | 0.61 |
| 8th 1,000 | 0.47 |
| 9th 1,000 | 0.32 |
| 10th to 14th 1,000 | 0.79 combined |
| Proper nouns | 2.05 |
The proper-noun block beats every single band from the fourth on. It's worth more than the 8th through 14th thousand families put together, and it costs nothing, because Madrid is Madrid in every language you'll ever read it in.
It doesn't beat the 4th and 5th combined (2.85) or the 6th through 14th combined (2.88). So the block is worth roughly two thousand-family bands at that point in the curve rather than the whole tail.
Cheerful for a learner, awkward for the statistic. The cheapest 2 points of coverage in the table are free, and they sit inside the number people use to measure how much studying they have left.
One caveat on Table 5 while we're inside it. The gap between its two columns should be constant at 2.05 on every row, since the same names get added each time.
It's 2.05 on 13 rows and 2.11 on the sixth. Almost certainly a typesetting slip, and I mention it because someone else will check.
The proper-noun clause gets sanded off at every hop
Nation isn't hiding any of this. His paper is free to read at lextutor.ca, no paywall, no login, and the caveats are in the conclusion rather than a footnote.
That openness is probably why his figures travel so far. It's also why the caveats get stripped: a free PDF is easy to skim and easy to quote from without reading past the number you came for.
Two live examples, both citing him properly.
Glossika's blog, dated 29 September 2022, writes that "a vocabulary of one-thousand words would allow you to recognize nearly 80% of the words in a given English text." It cites Nation 2006 with a direct link to that exact PDF.
The proper-noun clause is nowhere on the page. So the citation is honest, the link works, and the figure still arrives missing the condition that Nation attached to it in the same sentence.
Universe of Memory has "1000 words allow you to understand about 80% of the language which surrounds you, as long as it is not too specialized," citing Nation across several works. Same shape: careful attribution, no clause.
And "not too specialized" is doing the job the proper-noun clause should be doing, except it points at the wrong variable. Nation's own spread says the swing is between a novel and a newspaper, both of which are perfectly unspecialized.
Neither page is being careless on purpose. The clause is awkward to carry: "the first 1,000 words plus proper nouns cover 78 to 81% of written text" is a worse sentence than "1,000 words gets you 80%," and the second is what a reader wants. So it gets sanded off at every hop.
It's the same failure I found in the frequency list comparison. There, hablar occupies 38 separate rows spanning rank 154 to rank 47,098, because the list was never lemmatised (grouped so every form of a word counts once).
A number gets published with its counting rules attached, the rules are boring, and the number goes travelling alone.
Discount the names when you test your own coverage
Three things follow. The first is the useful one.
When you test your coverage on a text, discount the names. Take a page, count what you understand, then take the names out of that total.
On a newspaper you lose about 5 points, on a novel about 1.5. What remains is what your studying bought, and it's the number to track.
Second, pick your genre knowing what you're picking. A novel is the harder honest test and a newspaper the friendlier one.
If you want to feel progress, read news. If you want to measure it, read fiction.
Third, the limit of what I can support: everything above is English against BNC lists (word lists built from the British National Corpus). I have no equivalent table for Spanish, French, Italian or Portuguese. The genre logic should carry, since a Spanish newspaper is also about people and places. But "should carry" is a guess, and I won't dress it up with a decimal point.
One more honest limit: cheap isn't free. Madrid transfers, but a learner reading Spanish news meets Hacienda and la Moncloa, proper nouns carrying cultural content that RANGE (Nation's text-profiling program) counts as understood.
Nation flags the mirror-image error himself: "Bush is a proper noun, but RANGE treats it as an occurrence of the noun bush," which lands in the third 1,000. The tool is approximate at both ends.
Where Verbamor sits in this is narrow. It builds cards from your own lessons, so your deck holds whatever your tutor actually said rather than a frequency band. Names mostly don't enter, because you already know them.
That sidesteps the measurement problem rather than solving it. For a real coverage figure you want a text profiler and a page you've read, and both are free.
The next time you meet "1,000 words covers 80%," the question worth asking is 80% of what text. Nation measured 14 of them, and the names alone move the answer by five points.
Sources
The paper
- Nation, I. S. P. (2006). How Large a Vocabulary Is Needed For Reading and Listening? Canadian Modern Language Review, 63(1), 59–82. Full PDF retrieved and read 3 September 2026. Proper-noun rows: Table 6 novels, p. 71 (1.04, 2.05, 0.50, 2.12, 1.55); Table 7 newspapers, p. 72 (5.29, 5.66, 6.12, 5.43, 4.55); Table 8 Dorian Gray, p. 73 (5.55); Table 9 Shrek, p. 74 (147 tokens, 1.47%); Table 13 spoken, p. 77 (1.29, 1.03). Both-ways cumulative coverage: Table 5, p. 70 and Table 12, p. 76. Conclusion point 1 and Table 14, p. 79. The combined-novel figure of 1.53% is in his prose on p. 71. Quoted lines: "The Turn of the Screw has a very small number of proper nouns because there are only four major characters in the novel"; newspapers "are about people, places, and events"; "Note that Bush is a proper noun, but RANGE treats it as an occurrence of the noun bush, which is in the third 1,000."
The arithmetic, all mine
- Sorted range across the 14 texts listed: minimum 0.50%, maximum 6.12%, ratio 12.24. Novel mean 1.452% from (1.04 + 2.05 + 0.50 + 2.12 + 1.55) / 5. Newspaper mean 5.410% from (5.29 + 5.66 + 6.12 + 5.43 + 4.55) / 5, giving a ratio of 3.73. Gap between highest novel (2.12) and lowest newspaper (4.55) is 2.43 points.
- Table 5, without-proper-nouns column, reaches 96.96% at the 14th 1,000 and so never crosses 98 within the word-family bands. With proper nouns it crosses at the 9th 1,000 (98.22%). Table 12 reaches 97.78% without and crosses at the 7th 1,000 with (98.08%). Both tables carry a further "Not in the lists" row: without proper nouns that reads 97.92% for Table 5 (still under 98) and 98.53% for Table 12 (over it), so the band-level claim is stated with that boundary in the text rather than as an absolute. Marginal band coverage is the difference between consecutive rows of the same column: 7.21, 3.14, 1.78, 1.07, 0.69, 0.61, 0.47, 0.32 for bands 2 through 9, and 96.96 − 96.17 = 0.79 for bands 10 to 14 combined. The proper-noun block for that text is 82.93 − 80.88 = 2.05. Nation publishes cumulative figures only and does not present marginal steps anywhere.
- Extension to the other nine texts, my arithmetic on Nation's printed rows. Table 6 at 9,000 plus proper nouns, minus each novel's own proper-noun figure: 98.06 − 1.04 = 97.02, 98.22 − 2.05 = 96.17, 98.52 − 0.50 = 98.02, 98.47 − 2.12 = 96.35, 98.00 − 1.55 = 96.45. Table 7 at 8,000 plus proper nouns, minus each corpus's own figure: 98.31 − 5.29 = 93.02, 98.03 − 5.66 = 92.37, 97.60 − 6.12 = 91.48, 97.28 − 5.43 = 91.85, 98.05 − 4.55 = 93.50. One caveat I should state: this assumes the proper-noun share is additive at that band, which is how Nation's own two-column tables behave (the gap is constant down the column), but for these nine texts he prints only one column, so it is an inference from the structure of Tables 5 and 12 rather than a figure he published.
- Marginal comparison: the 2.05 proper-noun block for Lady Chatterley's Lover exceeds every individual band from the 4th (1.78) on, and exceeds the 8th through 14th combined (0.47 + 0.32 + 0.79 = 1.58). It does not exceed the 4th and 5th combined (2.85) or the 6th through 14th combined (2.88).
- Consistency check on Table 5: the column difference is 2.05 on 13 rows and 2.11 on the sixth (96.88 − 94.77). Cross-checks that passed: Table 5 rows against the Table 6 figures for the same novel (88.09, 95.06, 98.22 all match), and Shrek's 147 proper-noun tokens against a 9,984-token total, which gives 1.472% against Nation's stated 1.47%. Nation's prose on p. 75 gives Shrek at 4,000 plus proper nouns as 96.70% where his Table 12 says 96.74%; I used the table.
The figure travelling without its clause
- Glossika, How Many Words Do You Need to Know to Speak Another Language?, dated 29 September 2022. "A vocabulary of one-thousand words would allow you to recognize nearly 80% of the words in a given English text," cited to Nation (2006) with a direct link to the lextutor PDF. No mention of proper nouns anywhere on the page. Retrieved 3 September 2026.
- Universe of Memory, How Many Words You Should Know. "1000 words allow you to understand about 80% of the language which surrounds you, as long as it is not too specialized." Cites Nation across several works. No proper-noun clause. The page shows a "May 30" date without a year in the body; reader comments date to 2015 or earlier, so I have not asserted a publication year. Retrieved 3 September 2026.
Not verified
- Hu, M., & Nation, I. S. P. (2000), the source of the 98% threshold, is cited here only as Nation cites it. I did not retrieve that paper, so nothing above rests on its own numbers beyond the threshold value Nation uses.
- No proper-noun-separated coverage profile for Spanish, French, Italian or Portuguese was located. Every figure on this page is English text against Nation's BNC-derived lists, and the genre pattern is not demonstrated for any other language.
Measure what you actually learned.
Verbamor builds cards from your own lessons, so your deck holds the words your tutor used rather than a frequency band.
Start 7 days freeThe 7-day free trial is on the yearly plan.