 Verbamor
The 90% retention target is an artifact of the objective
No single desired retention is optimal: on one deck with identical parameters, my port of the FSRS optimiser recommended 0.70 under two objectives and 0.95 under a third, and none landed on Anki's 90% default. The button that computed your own number is documented as removed in version 25.07. I set 0.85 and leave it for three months.
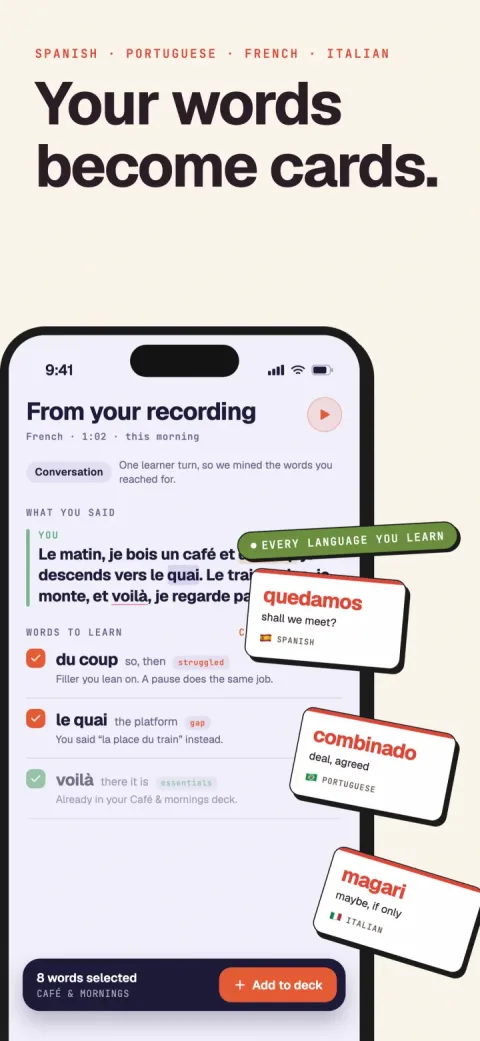
Verbamor turns the words from your own lessons and recordings into flashcards, and brings each one back before you’d forget it.
Anki's deck options page calls desired retention "the most important setting in FSRS" and ships it at 90%. Desired retention is the recall rate the scheduler aims for when a card comes due, and FSRS is the scheduling algorithm Anki offers.
So people tune it, forums argue 85 against 90, and guides print a recommended value with the confidence of a spec sheet.
Anki's own manual has marked the tool that computed the optimum as a removed feature since 25.07. And the number it would have given you depends entirely on a question rarely asked out loud: optimal for what?
Where did Anki's retention calculator go?
Compute Minimum Recommended Retention, CMRR for short, got folded into Anki's simulator, and the manual now lists it as removed. You clicked it, it simulated a year of your deck at various retention levels, and handed back a number. Anki's manual now carries this, under a heading reading "Compute Minimum Recommended Retention (<25.07)":
Removed Feature
This feature has been removed as of anki version 25.07
25.07 shipped on 4 July 2025, so the CMRR button has been documented gone for a year.
Two honest complications on CMRR's removal. The first: the manual contradicts itself.
About 100 lines above that removal notice, the section on switching FSRS on still tells you to use "Compute minimum recommended retention" to choose the value. Both sit in the same file.
The second: the CMRR code didn't vanish. I checked Anki's source at tags 25.02, 25.07, 25.09 and 26.08.
The CMRR calls move out of FsrsOptions.svelte at 25.07 and reappear in a new file, SimulatorModal.svelte, still there in 26.08. The optimiser also survives in the FSRS Rust library as a public function, optimal_retention.
So: CMRR stopped being a labelled button beside the setting it configures, got folded into the simulator, and the manual declared it removed. The engine is still there, and the docs no longer call it a supported way to pick a number.
One deck gives three different optimums, one per objective
The FSRS optimiser doesn't find "the" optimum. It minimises a target function you hand it, and in the current source that function is a swappable argument called CMRRTargetFn. Change it and you change the answer.
The project's wiki says the target changed once already: "Before Anki 24.04, the goal was to maximize knowledge acquisition (the sum of all probabilities of recall), but in Anki 24.04+, the goal is to minimize workload/knowledge (minutes of studying divided by the aforementioned sum)."
I wanted to know how much swapping the target function moves the answer, so I ported the simulator to Python from the source.
FSRS-6 defaults and decay came from inference.rs, the forgetting curve and stability transitions from analytic.rs, and the review loop, cost table and rating probabilities from simulation.rs.
Then I swept desired retention from the legal floor of 0.70 to the ceiling of 0.95 in steps of 0.01. I ran three seeds (separate random runs) each, 3,650 cards over 365 days at 10 new cards a day.
Before trusting my port I checked it against the library's own test. test_optimal_retention asserts the optimiser returns 0.7, and my port bottoms out at 0.70.
These are still a model's numbers about itself. No one's memory was measured.
Three objectives, one deck, one parameter set:
Minimise study time per unit of knowledge (the Anki 24.04+ target) → 0.70
Minimise raw study time → 0.70
Maximise knowledge (the pre-24.04 target) → 0.95
The full span of legal values, decided by which question you asked. And neither answer is 0.90: the default sits between two defensible ends.
Parameters move the optimum too, and the FSRS library says so itself. A second test, test_optimal_retention_with_old_parameters, holds the objective fixed and swaps in an older parameter set. It asserts an optimum of 0.75508595: 5.5 points off the 0.70 the first test asserts.
That test is switched off, tagged #[ignore], "temporarily disabled while optimal retention behavior is being reviewed".
Why does the knowledge objective run to the ceiling? Knowledge, the sum of recall probabilities, rises with every step up in retention. So "maximise knowledge" always says review more.
What each setting costs (DR is desired retention), averaged over three seeds:
DR 0.70 → 19.2 min/day, knowledge 2,991
DR 0.80 → 22.5 min/day, knowledge 3,268
DR 0.85 → 25.0 min/day, knowledge 3,372
DR 0.90 → 29.4 min/day, knowledge 3,471
DR 0.95 → 41.0 min/day, knowledge 3,564
Take the steps either side of the default. 0.90 to 0.95 buys 2.7% more knowledge for 39.6% more time.
Down to 0.85 gives up 2.8% and returns 14.9% of your time. Down to 0.70 gives up 13.8% and returns 34.8%.
The top of the range is priced terribly, which is why any objective with time in the denominator walks to the floor.
On any given day, you recall more of your cards than your setting says
A second confusion sits underneath the objective question, and it's why people misread their stats screen.
Desired retention is the probability you'll recall a card at the moment it comes up. Average retrievability is the probability you'd recall a card picked at random today, and most cards aren't due today.
Expertium: desired retention is "I will recall this % of cards WHEN THEY ARE DUE", average retrievability is "I will recall this % of ALL my cards TODAY".
Average retrievability is always higher than desired retention. Integrating the FSRS-6 forgetting curve across one full interval, with decay 0.1542 and the factor that makes retrievability hit 0.9 at one stability:
DR 0.95 → average retrievability 97.3%
DR 0.90 → 94.4%
DR 0.85 → 91.0%
DR 0.80 → 87.3%
DR 0.70 → 78.9%
My 94.4% at a 0.90 setting sits within rounding distance of the 94.7% Expertium reports, which is the check I wanted on my own arithmetic.
So 0.85 still leaves you knowing about 91% of your vocabulary on a given day, less frightening than "15% forgotten" sounds. And a pass rate near 94% on a 90% target means the scheduler is working. A rate well above that is a sign it's scheduling you too early rather than too late.
The popular 85% has no source in the FSRS docs
Search desired retention and you'll meet a confident claim: the optimal desired retention is 85%, below the default 90%.
The FSRS wiki page on optimal retention, which documents the entire CMRR method, names no recommended value at all. It gives the shape of the curves and this warning: "the following graphs are generated from the default parameters of FSRS. The real graphs vary among different learners."
The Y axes are deliberately unlabelled, because the values "depend on many things (FSRS parameters, time spent per card, deck size, new card limit, etc.)".
So the FSRS wiki, the canonical source for the optimum, publishes no optimum. The 85% is folklore attached to a page that declines to give a number, and my sweep puts the cost-minimising answer at 0.70.
The honest reading: there's no universal answer, the curves are personal, and the tool for finding your own is no longer a supported button.
There's a real 85% in the literature, and it doesn't rescue the folklore.
Wilson, Shenhav, Straccia and Cohen published "The Eighty Five Percent Rule for optimal learning" in Nature Communications in 2019. It derives an optimal training error rate of ER* ≈ 0.1587: "the optimal error rate for learning is 15.87%, and the optimal accuracy is around 85%."
Read the scope line of the Wilson paper. The result holds "for a broad class of learning algorithms in the context of binary classification tasks", specifically "stochastic gradient-descent based learning algorithms".
The words "forgetting", "flashcard" and "retention" appear zero times in the paper. Nothing in it models memory decaying over an interval, the entire thing FSRS schedules around.
The Wilson paper even names a case where the sweet spot disappears: a Bayesian learner with perfect memory "would learn equally well if hard or easy examples are presented first". The 85% is a property of one kind of gradient-following learner.
Wilson and colleagues do connect their result to Desirable Difficulties, the framework covering "spacing practice over time". But they call these "related, but distinct".
And they say plainly that "no formal theoretical work has addressed the effect of training accuracy on learning, a test of which is an important direction for future work".
One thing cuts the other way: the paper notes that staircasing procedures (tests that adjust difficulty as you go) are "commonly designed to produce about 80–85% accuracy".
The intuition is shared, and the derivation isn't. Treat the two 85% figures as a coincidence of numbers until somebody runs the test the authors called future work.
I’d set 0.85 and leave it for three months
Ending on a shrug would waste your time. The dial has to sit somewhere, so here's a starting point. It's no universal optimum, since the tests above show there's none.
Set 0.85, and leave it there for three months.
Three reasons for 0.85. The arithmetic is lopsided: 0.85 costs 2.8% of knowledge and returns 14.9% of study time on the shipped defaults.
Every objective with time in it wants you below 0.90. The two reaching the floor at 0.70 ignore that a deck you resent is a deck you abandon. 0.85 is where I stop trusting a simulator with no term for motivation.
A 0.85 setting also stays where the model has evidence. FSRS clamps desired retention to 0.70 through 0.95, and the manual warns that "above 90% the workload increases very quickly, and above 97% the workload can be overwhelming". A notch below the default sits well inside it.
And 91% average retrievability, what 0.85 delivers day to day, is a fine place for a language learner to live. You'll fail about one card in seven: uncomfortable enough to be real work, mild enough that sessions don't rot.
Two cases where I'd move off 0.85.
With a fixed exam date, go to 0.90 and accept the bill: the knowledge curve keeps climbing, and a deadline outranks efficiency.
If reviews have outgrown your time, go to 0.80 before deleting cards. It returns 10% of your time, and losing 3.1% of recall beats abandoning the deck.
What I wouldn't do is retune desired retention monthly. The tool that could measure your own optimum is documented as removed.
The objective is a design choice, with no law of memory behind it. And the gap between 0.85 and 0.90 is smaller than the gap between studying and not.
For the layer underneath, the three numbers FSRS tracks per card explain where stability comes from, and how many cards a day is the other half of the workload question.
Verbamor runs FSRS at the 0.90 default and doesn't expose this dial, a deliberate trade worth naming.
Our learners are capturing words from tutor lessons. A setting whose optimum depends on an objective function is one I'd rather keep away from someone who just wants yesterday's vocabulary to stick. If you want to tune it yourself, Anki is the better tool, and that's a real reason to pick it.
The 90% in Anki's desired retention box was never measured on you. Somebody chose it while optimising something, and knowing which separates tuning from copying a stranger's homework.
A dial you never have to touch.
Verbamor runs FSRS at the 90% default and spends its effort on the part that actually decides whether a word sticks: catching it from your real lessons, with the sentence you met it in.
Start 7 days freeThe 7-day free trial is on the yearly plan.