 Verbamor
The FSRS benchmark does not contain SM-2
Every page claiming FSRS beats SM-2 links the same benchmark. Neither of its two published result tables has an SM-2 row. The numbers do exist, in files nobody quotes, so I aggregated them myself and worked out what a difference in these metrics is and isn't worth.
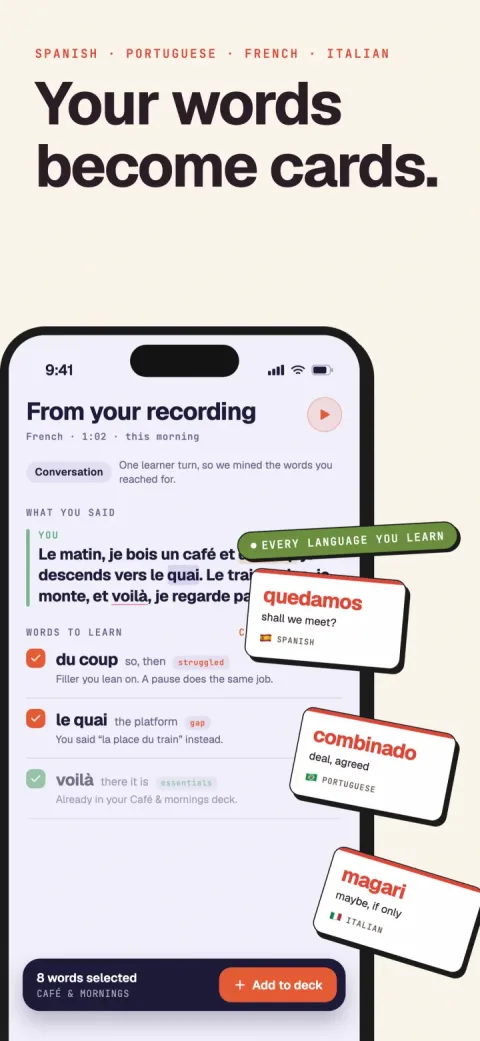
Verbamor turns the words from your own lessons and recordings into flashcards, and brings each one back before you’d forget it.
There's a number everyone quotes. FSRS beats SM-2 for 99.5% of users, and that buys you 20 to 30% fewer reviews at the same retention. Both halves get sourced to the open-source SRS benchmark run by the FSRS developers.
(FSRS is an open-source algorithm that predicts when you're about to forget each card. SM-2 is the 1987 algorithm behind Anki's legacy scheduler.)
So I went to read it. It publishes two result tables, one excluding same-day reviews and one including them. I counted 31 algorithm rows in the first and 29 in the second.
Not one of them is SM-2.
The SM-2 results do exist, sitting in the repository. And the benchmark's authors have written about their limits more honestly than any page citing them. The honesty just lives in one place and the citations point at another.
The published tables have no SM-2 row
The benchmark is open-spaced-repetition/srs-benchmark on GitHub, and its README is the artifact everyone links. Every figure below comes from the commit of 29 August 2026.
Its scope is large: 9,999 Anki collections and 349,923,850 reviews used for evaluation, drawn from a public dataset of about 727 million. That's most of the usable spaced repetition telemetry that exists in the open.
The top of the main table, lowest log loss first:
| Algorithm | Params | Log loss | RMSE (bins) | AUC |
|---|---|---|---|---|
| RWKV-Instant | 2,762,884 | 0.2773 | 0.02502 | 0.8329 |
| GRU | 503 | 0.3328 | 0.0549 | 0.7324 |
| FSRS-7 recency | 34 | 0.3370 | 0.0593 | 0.7220 |
| MOVING-AVG | 0 | 0.3369 | 0.05915 | 0.7001 |
| FSRS-6 | 21 | 0.3460 | 0.0653 | 0.7034 |
| FSRS v4 | 17 | 0.3726 | 0.0838 | 0.6853 |
| AVG | 0 | 0.3945 | 0.1034 | 0.4997 |
| HLR (Duolingo) | 3 | 0.4694 | 0.1275 | 0.6369 |
Fourteen FSRS variants. Two neural networks. Duolingo's half-life regression. Two baselines that model nothing. No SM-2.
What the repository does hold is result/SM2.jsonl, one line per user, 9,999 lines, exactly matching the collection count in the published table. There's a matching result/Anki.jsonl, and both have plot files in plots/LogLoss/.
The code path is live too: models/sm2.py implements the 1987 algorithm in 35 lines. Everything needed to publish the row is there. It isn't published.
All three metrics score predicted recall, and none scores workload
"More accurate" is doing unexamined work in the pages quoting these columns. All three metrics score one thing: how well an algorithm predicts the probability that you'll recall a card. Nothing about intervals, workload, or study time.
Log loss is the penalty for confident wrongness. Predict 90% and be right, small penalty. Predict 90% and be wrong, large one. It's what the Anki optimizer minimises internally.
RMSE (bins) is calibration. Reviews get grouped into bins by interval length, review count and lapse count. Within each bin, the average predicted recall is compared to the average recall that actually happened.
The benchmark's own maintainer describes it as "the average difference between predicted and measured probability of recall (R)", so its units are percentage points of recall probability.
AUC is ranking. Given two cards, how often does the algorithm correctly say which you're more likely to remember? It ignores whether the probabilities are right in absolute terms.
The benchmark README states the trap plainly: "AUC can be good (high) even if Log Loss and RMSE are poor." An algorithm can order your cards perfectly and still be badly wrong about when you'll forget them.
The unpublished files put SM-2 far behind on all three metrics
The per-user files are plain JSON lines with a metrics object. Aggregating them needs the method the README uses, and the README doesn't state one. So I worked it out by reproduction, testing candidates against rows the README does publish and keeping the one that matched.
I took an unweighted mean across users, with a 99% normal confidence interval (the range the true value most likely sits in). It reproduces the published FSRS-6 row as 0.3460 ± 0.0042 and 0.0653 ± 0.0011, the printed values to four decimals. It reproduces FSRS-7 recency in the same-day table as 0.3178, 0.05715 and 0.7522, again exact. Summing the per-user review counts gives 349,923,850, the README's own total to the digit.
Three independent checks, three exact matches. Running the same aggregation on the unpublished files:
| Algorithm | Log loss | RMSE (bins) | AUC | Published? |
|---|---|---|---|---|
| FSRS-6 | 0.3460 | 0.0653 | 0.7034 | Yes |
| Anki (trainable SM-2, 7 params) | 0.5127 | 0.1419 | 0.6233 | No |
| SM-2 (1987, as specified) | 0.7220 | 0.2031 | 0.6026 | No |
Same 9,999 collections, same reviews, same aggregation.
A distinction worth keeping: the benchmark carries two SM-2 implementations. Plain SM-2 has no free parameters. The one labelled Anki is a 7-parameter version fitted to each user's history, a considerably fairer opponent, and it lands roughly halfway between.
Per user, FSRS-6 has the lower log loss for 99.7% of collections against plain SM-2 and 98.8% against the trainable Anki variant. The widely quoted 99.5% is about right, and it's the only part of the popular claim that survives contact with the data.
SM-2's bias is the only number here with a workload cost
Here's the step that needs care. RMSE (bins) is quoted in probability units, so it's tempting to multiply it by a review count and report cards. That doesn't work: it's a root-mean-square over bins, not a per-review average, so a few badly-calibrated bins dominate it.
The per-user files carry two metrics the README never prints. ICI is computed in the benchmark's own code as np.mean(np.abs(p_calibrated - p)). That's the mean gap between what the algorithm predicted and what a calibration curve fitted to the real outcomes says it should have.
MBE is the mean of predicted minus actual, which carries the direction every squared metric throws away.
| Algorithm | ICI (mean per-review error) | MBE (predicted − actual) |
|---|---|---|
| FSRS-6 | 0.0313 | +0.0023 |
| Anki (trainable SM-2) | 0.0961 | not recorded |
| SM-2 (1987) | 0.1541 | −0.0874 |
FSRS-6's predictions sit an average of 3.1 percentage points from the truth per review. Plain SM-2's sit 15.4 points away, Anki's trainable variant 9.6.
I went looking for a way to turn that into cards per day. It can't be done from these metrics.
ICI measures the distance between a model's stated confidence and its own calibration curve. So it scores miscalibration only, and a model with no skill at all can do well on it.
The benchmark proves that itself. AVG predicts your average retention on every card and nothing else, so its AUC is 0.4997, a coin flip. Its ICI is 0.0544, comfortably better than SM-2's 0.1541.
Multiply either by a review count and you get total probability error, not cards. Converting a calibration metric into review workload converts something that isn't in it.
MBE is the one that survives, and it's the more useful finding anyway. At −0.0874, SM-2 under-predicts recall by 8.7 points. So it thinks you'll forget more than you do, and schedules accordingly. FSRS-6 sits at +0.0023, essentially unbiased.
That bias, rather than any calibration noise, is the mechanism behind every anecdote about SM-2 burying people in reviews. It's the only number here carrying a workload consequence.
Now the comparison people face, between FSRS versions rather than eras. Recency weighting runs on the same 9,999 collections: RMSE (bins) 0.0653 to 0.0629, log loss 0.3460 to 0.3444, ICI 0.0313 to 0.0285.
That last one has units: 0.28 percentage points of average prediction error, against the 12.3 points separating FSRS-6 from SM-2. The era gap is 44 times the version gap, and that ratio is the honest headline.
Both numbers are honest. A 12.3-point error in stated confidence is a difference in kind. A 0.28-point one is a difference you'd never detect from your own review log. Quoting a relative percentage without the absolute one is what makes those sound like the same kind of finding.
Log loss anchors the same way. A perfectly calibrated forecaster saying 90% scores 0.3251. The FSRS-6 to SM-2 gap of 0.376 is roughly what you'd pay for saying 50% when the truth is 90%. The gap to recency weighting, 0.0016, is what you'd pay for saying about 88%. A four-decimal table hides that.
If you want intervals rather than probabilities, that's a separate table entirely, and it's the one the "20 to 30% fewer reviews" claim would need.
Four findings in the same tables cut against FSRS
Four findings from the same tables cut the other way.
MOVING-AVG ties the winner. It has zero parameters and no model of memory, and outputs a number that rises after successes and falls after lapses. It scores 0.3369 log loss against FSRS-7 recency's 0.3370, and 0.05915 RMSE against 0.0593, beating every FSRS version up to FSRS-6.
The benchmark includes it as a sanity floor, and the floor is level with the ceiling.
The best result isn't FSRS. RWKV-Instant, a 2.7-million-parameter neural network, is far ahead at 0.2773 log loss and 0.8329 AUC. It gets extra input features and doesn't use the same time-series split, both disclosed in the README. Still, the algorithm that wins the FSRS benchmark isn't FSRS.
Default parameters cost more than a version upgrade. FSRS-7 with default parameters scores 0.0910 RMSE against 0.0593 optimised. That 3.2-point gap dwarfs any gap between adjacent versions. Which version you run matters far less than whether you've pressed Optimize, and that finding sits underneath all 21 parameters.
The SuperMemo comparisons don't separate anything. Those head-to-heads live in separate repositories, and the SM-17 one runs on 19 users against 9,999 in the headline. Its confidence intervals swamp the result: FSRS-6 at 0.367 ± 0.040 log loss, SM-17 at 0.432 ± 0.084. Anyone citing the big benchmark as evidence about SuperMemo is citing 19 people.
The benchmark supports better prediction and never measured workload
The FSRS team's own writing is careful in a way the citations aren't. The benchmark's co-author writes: "There is no way to have a truly fair, no caveats, comparison between FSRS and SM-2."
The reason is structural. SM-2 was never designed to output probabilities, so the benchmark bolts on "a not-so-rigorous interval-to-probability converter". SM-2 is scored on a task it was never built to do.
Which leaves the popular claims in three piles.
Supported. FSRS predicts recall better than SM-2 for around 99% of collections. That holds on 9,999 users, and against the trainable Anki variant too.
Not measured. Fewer reviews at the same retention. The benchmark reports log loss, RMSE and AUC, and no intervals, workload or study time at all. The "20 to 30%" figure comes from scheduling simulations, and pages attribute it here anyway.
Wrong. That FSRS is Anki's default. The manual still calls it "an alternative to Anki's legacy SuperMemo 2 (SM-2) algorithm". It tells you to "Enable FSRS under the 'FSRS' section, at the bottom of the deck options page". Built in since 23.10 is true. Default isn't.
If you've never opened that page, none of this has run on your cards.
One caveat applies to every number above: the dataset is Anki users who opted in. Language learners aren't separated out.
My own reading is that the algorithm question is close to settled and close to unimportant. The distance from SM-2 to FSRS is real and worth the toggle.
The distance between recent FSRS versions is a third of a percentage point, and the gap between optimised and default parameters is several times larger. What you put on the card is a bigger lever than all of them, which is the same conclusion the retention setting reaches from the other direction.
Verbamor runs FSRS on every card, fitted to your own reviews, with no toggle to find. That's worth about what this post says it's worth. It removes a setup step and puts you on the right side of the one gap here that's large.
The cards come from your own lessons and conversations, which is the part I'd argue about. The scheduler is the part I wouldn't.
Sources
- Open Spaced Repetition. srs-benchmark. README as of the commit of 29 August 2026, plus
result/SM2.jsonl,result/Anki.jsonl,result/FSRS-6-short.jsonl,result/FSRS-6-short-recency.jsonl,result/AVG.jsonl,models/sm2.pyandutils.py, where the ICI and MBE definitions live. - Open Spaced Repetition. The Metric. Definitions of log loss, AUC and RMSE (bins), including the binning formulas.
- Expertium. Benchmark of Spaced Repetition Algorithms. Source of the RMSE (bins) interpretation, the interval-to-probability caveat and the 99.6% superiority figure.
- Open Spaced Repetition. fsrs-vs-sm17. The 19-user SuperMemo comparison, with its own metric tables.
- Anki. Deck options manual. The FSRS section, verified live on 3 September 2026.
The scheduler you don't have to configure.
Verbamor runs FSRS on every card, fitted to your own reviews, with no toggle to find and no parameter box to fill in.
Start 7 days freeThe 7-day free trial is on the yearly plan.